Cohort Analysis Dashboard
▶ Data-flow diagram — self-contained HTML, opens in a browser — no install, no build
Situation
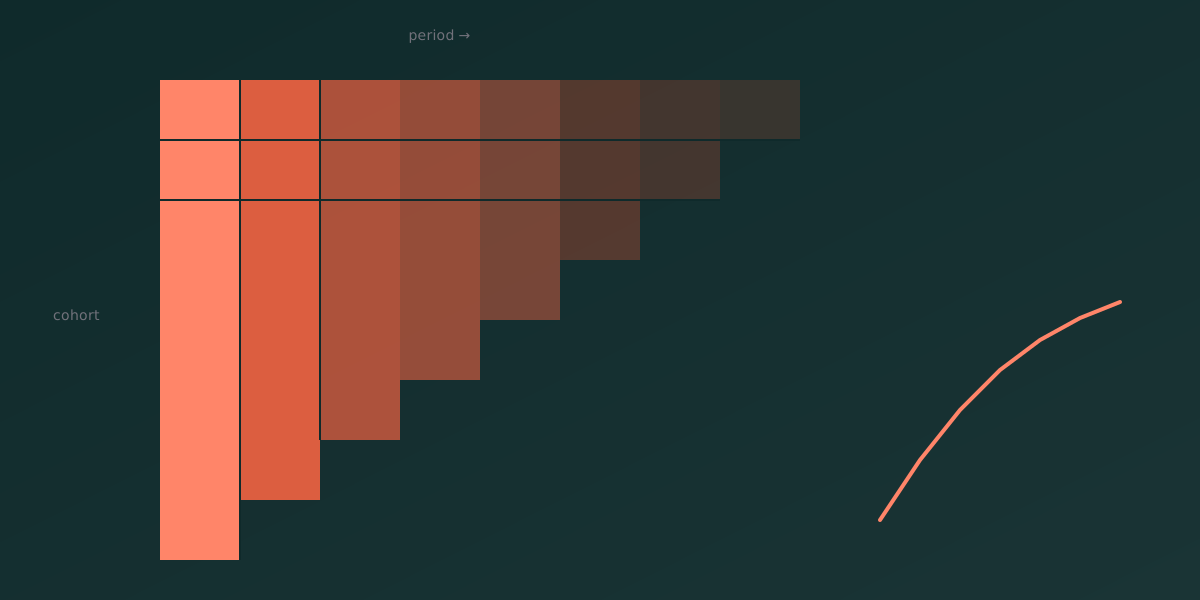
Cohort retention and LTV analysis on synthetic data: user retention, churn curves, and revenue by acquisition cohort. Average retention hides the dynamics, and LTV without accounting for cohort age misleads — so the matrix carries the observation-age caveat and the comparable metric is the fixed-horizon LTV (ltv_at_k). The task is to build a matrix that shows where churn speed is higher and where monetization drops faster than retention. A Python pipeline (pandas + matplotlib/seaborn) plus a Tableau-ready export; data is synthetic and deterministic (seed=42), reproduced from code.
Task
I needed retention and lifetime value to be readable per acquisition cohort rather than as a single average, so I owned the pipeline that turns synthetic data into a retention and revenue matrix ready for Tableau.
Actions
Data model — one row = “user × observation month”:
| Field |
Type |
Description |
user_id |
int |
user identifier |
cohort_month |
date |
arrival month (derived from join_date, not a separate field) |
join_date |
date |
registration date (first of month) |
period |
int |
months since arrival (0 = registration month) |
is_active |
int 0/1 |
active in this month |
revenue |
int |
revenue for the month (0 if inactive) |
cohort_month is derived from join_date, as in real production. Younger cohorts have fewer observed months — the retention matrix is triangular.
Methodology:
- Period 0 = 100% retention by definition (all active in arrival month). The curve decays from period 1:
retention(p) = 0.85 · 0.75^(p-1).
- Revenue: active month →
Poisson(λ=10); inactive → 0.
- Cohort sizes — count of unique
user_id where period == 0.
- ARPU — average revenue per cohort user; LTV — cumulative ARPU over periods.
Functions: cohort_sizes() (monthly inflow), retention_matrix() (matrix + curves), revenue_by_cohort() (ARPU/LTV).
Real data: real_data.py accepts a CSV on the same “user × month” contract — fail-fast validation (required columns, types, duplicates, period-0 coverage), with PII (email, phone, name) dropped by whitelist.
Tableau export (tableau_export.py) creates in tableau/:
cohort_export.csv — flat shape for Tableau (adds cohort_label and period_date — the calendar observation month);cohort_extract.hyper — a Tableau Hyper extract via the official Hyper API.
Tableau heatmap: Columns = period, Rows = cohort_label, Marks = Square, Color = AVG(is_active), Text = % of Total per row.
Result
The cohort view matters more than average retention: it exposes churn speed and where monetization diverges from it. The key methodological choices — cohort_month is derived from join_date (not a separate random field), period 0 = 100% by convention, and NaNs are masked in the heatmap instead of rendering nan%.
- Python inside Tableau: 4 calculations are deployed to a TabPy server (localhost:9004) by
tabpy/deploy.py — 6 endpoints, with Python executed inside Tableau.
- Tests: 65 (26 tabpy + 16 real_data + 14 cohort_analysis + 9 tableau_export) keep the pipeline reproducible.
Limitations
LTV of younger cohorts is understated due to short history — compare LTV correctly only at equal cohort “age.” The data is synthetic, so the numbers illustrate the method, not the behavior of a real product.